Toxicity Filter Upgrade
We’re upgrading the AI Assistant’s toxicity filtering to consider the full context of a conversation rather than evaluating content in isolation. This provides a more accurate understanding of user intent and helps identify genuinely harmful content.
The upgrade also reduces false positives, allowing safe conversations to continue without unnecessary interruption.
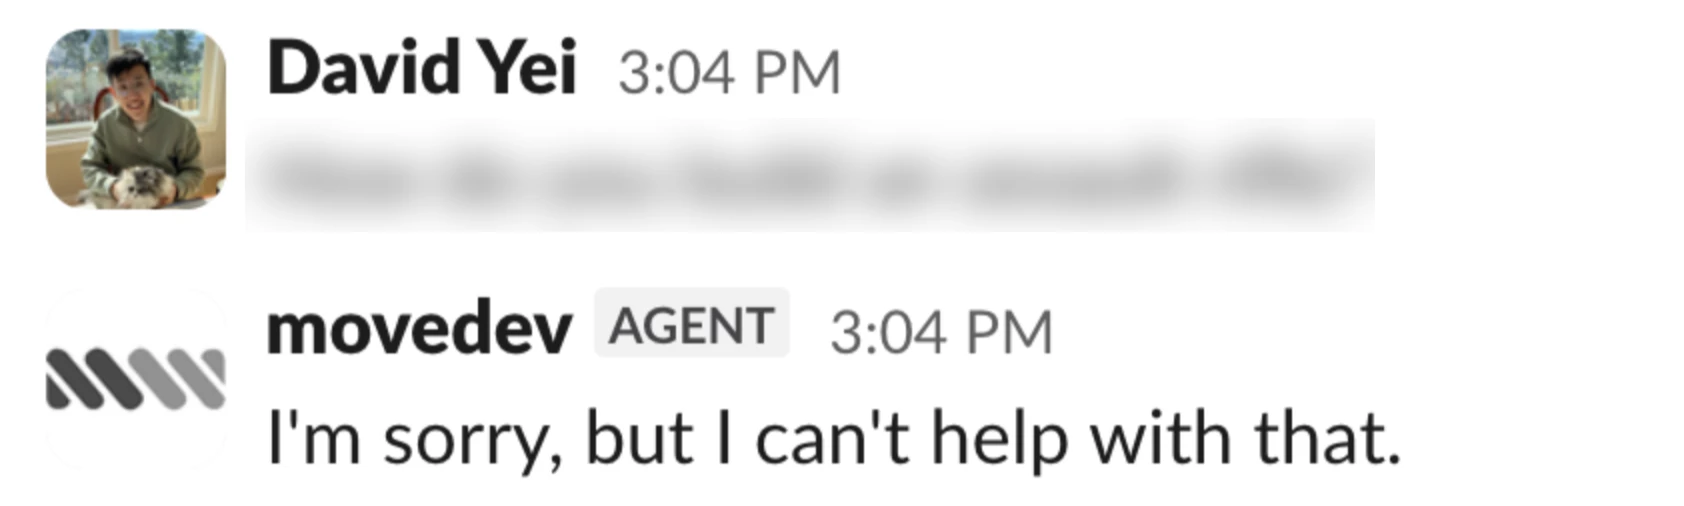
Example Output
Content safety is now handled directly by the Assistant's reasoning engine, which evaluates each request in the full context of the conversation. Instead of a context-blind checkbox, the Assistant understands what you're actually asking for before deciding whether it can help. When a request genuinely crosses a line, the Assistant issues a clear, consistent refusal.
The old "Specific Topic Toxicity" model, with its fixed five fixed categories, has been replaced by a free-form custom topic prompt. In the new model, six categories remain blocked by default in the background, and you can now add your own on top of them.
Default blocked categories
These six categories are blocked by default for every organization:
- Violent — physical violence
- Non-violent Illegal Acts — requests to carry out unlawful activity that isn't violent
- Sexual Content — sexually explicit content
- Unethical Acts — content promoting unethical behavior
- Politically Sensitive — contentious political content
- Jailbreak — attempts to bypass the Assistant's safety instructions
Note: Core anti-jailbreak protections always remain in place and cannot be overridden.
Rollout Schedule/ Tiers
Frontier: 9/2/2026
Standard: 9/8/2026
Basic: 9/10/2026
What improved
- Far fewer wrongly-blocked requests. The old filter frequently flagged benign messages as unsafe. Across 5,000+ live production conversations, the new approach produced zero user-visible false refusals, so legitimate requests get answered.
- Better at catching genuinely unsafe content. On calibrated safety benchmarks, the new approach catches roughly twice as much truly harmful content as the previous filter.
- Context-aware judgment. The Assistant can now tell the difference between, for example, "a colleague is harassing me, how do I report it?" (helped) and harassing content itself (refused). It also holds up regardless of framing, whether fiction, roleplay, hypotheticals, or jokes.
- Broader, more sensible coverage. Requests like "help me download movies and software without paying" are now correctly declined.
- New: per-organization safety customization. Enhanced content-safety control for your organization.
Every other aspect of the Assistant's behavior is unchanged. This only affects when and how genuinely unsafe requests are declined.
How to check it out in your org
See it in action. No setup required. The upgraded safety behavior is enabled for your organization automatically as part of our staged rollout. You can simply keep using the AI Assistant, and legitimate requests that may have been over-blocked before should now go through cleanly.
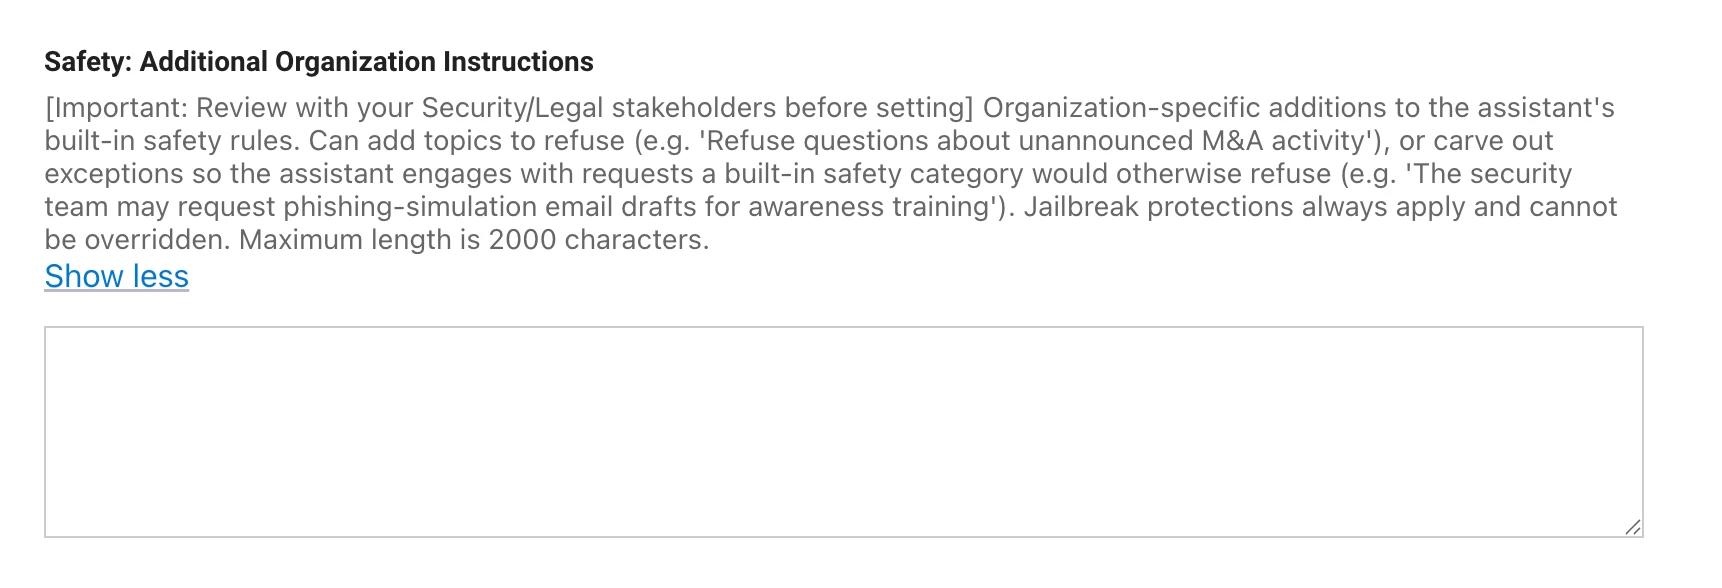
Customize safety rules for your organization. A new Additional Organization Safety Instructions setting lets you extend the built-in safety categories with your own rules. For example:
Find in: Chat Platforms -> Display Configurations > Moveworks AI Assistant Display Settings & Disclaimers > Safety Guard: Allowed Content Categories
New Administration
Old Administration (Replaced)
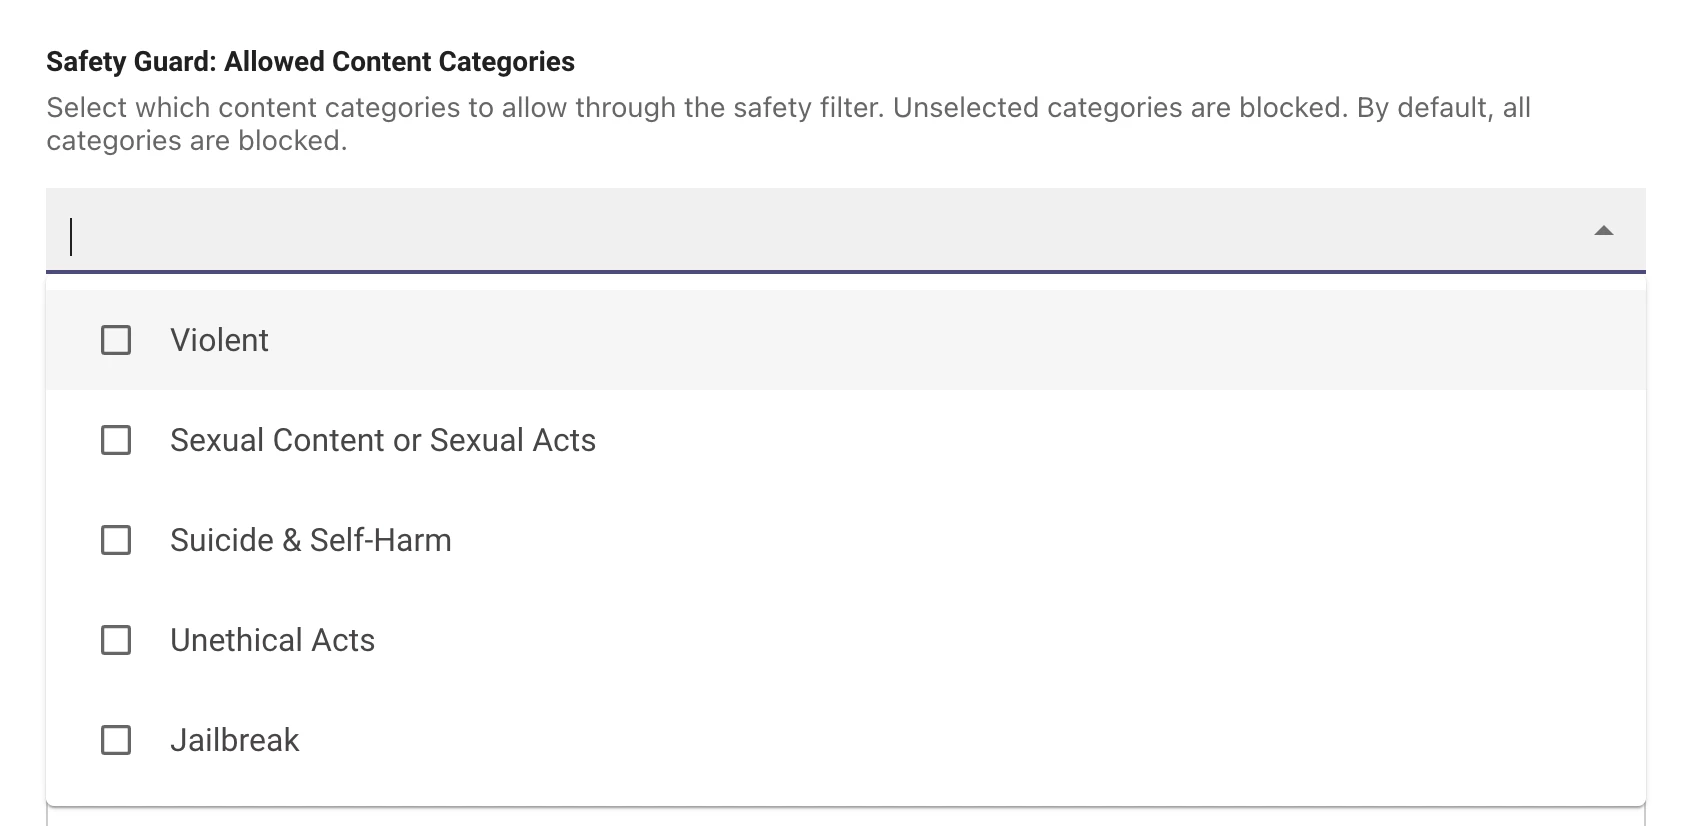
Update Settings if Needed: This free-text setting replaces the previous category allow-list. If your org previously configured the content-safety categories, you will want to customize the new instructions accordingly.
- Adding topics your organization wants the Assistant to decline, or
- Defining approved exceptions (for example, authorizing your security team to request phishing-simulation drafts for awareness training).
More information in the help documents here.